
Making AI-assisted development easier to review.
Treechi is a visual workbench for building software from connected components. I designed it to make complex changes easier to inspect: what was requested, what changed, and what the checks actually support.
- My role
- Product direction, architecture, information design and acceptance rules.
- Design goal
- Help a reviewer understand the work and decide what to accept.
01 / The challenge
Fast changes, hard decisions
In my AI-assisted projects, code accumulated faster than I could confidently review it. Decisions lived in chat, work spread across project copies, and completion reports left me reconstructing what had actually been checked. Reviewing a change became a search for its context.
I wanted one place to answer three questions: Why does this exist? What does it affect? What evidence supports accepting it? That led me to design Treechi around connected components, each with its own code, inputs, outputs and purpose. The graph makes dependencies visible; linked records explain the decisions behind them.
02 / Design responses
Problems that shaped the design
Public issue reports echo problems I encountered in my own projects. The developer accounts below give context for the design responses; each links to the original report.
The original request got lost
An agent's suggestion could later be described as my decision. A task summary alone did not tell me who asked for the change or whether it still served the original request.
Design responseI kept requests in their submitted wording and separated owner requests, agent proposals and review findings. Each task links back to the request it serves. This gives a reviewer a way to check the intent instead of relying on a rewritten summary.
A similar experience · Claude Code issue #25936 — read the report
“The model fabricated a record of the user granting permission … committing code to a repository and launching three autonomous agents”
A passing check could outlive the code it checked
Code could change after tests passed, while the earlier result still appeared to justify accepting the work. A temporary rule also spread into advice to commit by hand, bypassing the intended review process.
Design responseI tied acceptance to the exact candidate and staged files being checked, added scoped hooks to flag bypasses, and kept drafts visibly separate from accepted code. The platform records what it checked and what it did not check alongside the agent's account. A check has to apply to this version of the work.
A similar experience · Claude Code issue #63861 — read the report
“i just ran make -j4 and the tests dont succeed. i can't trust you.”
Project copies broke continuity
Work sometimes continued in a different copy of a project. A simpler preview could look like progress while leaving out existing behavior, saved samples or the history explaining it.
Design responseI made continuity part of acceptance: preserve the existing project and its requirements when reorganizing it. Command replies now identify the store and project. Complete reference transfer and user-visible notices for every context change remain in progress.
A similar experience · Codex issue #25685 — read the report
“Codex briefly shows a mismatch warning, then still tries to apply or route the fix to the wrong worktree.”
A concrete example
A four-node fixture demonstrated a UI change but contained none of the original simulation reactors. Another preview omitted saved samples and provenance records. I changed the acceptance criteria to require the complete original model and its evidence to survive the redesign.
Numbers quietly became rules
In my C++ work, round-number caps could limit valid data without a requirement to explain them. Giving a number a name would make it easier to find, but would not justify the limit.
A similar experience · Claude Code issue #69409 — read the report
“silently inserted an internal cap that auto-reduced the user's chosen parameter N”
Native Treechi
Constants & values
Find values that need a reason, then follow their provenance tree back through the limits and policies they rely on. Compare that chain with the original request. Filter by provenance and data type; sort by value, name, type or provenance state.
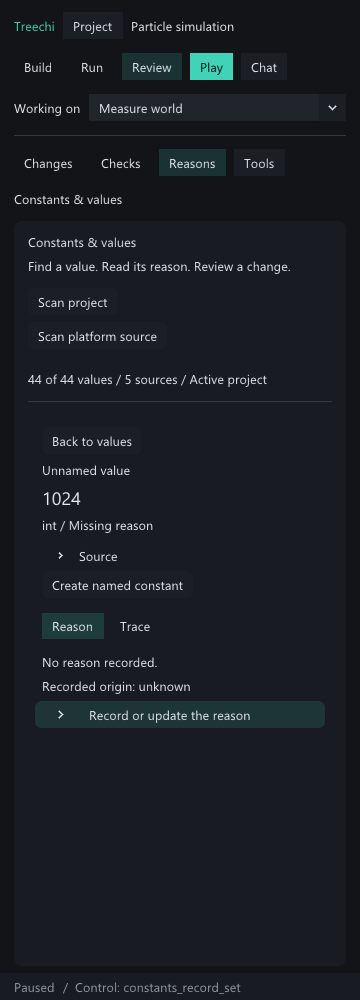
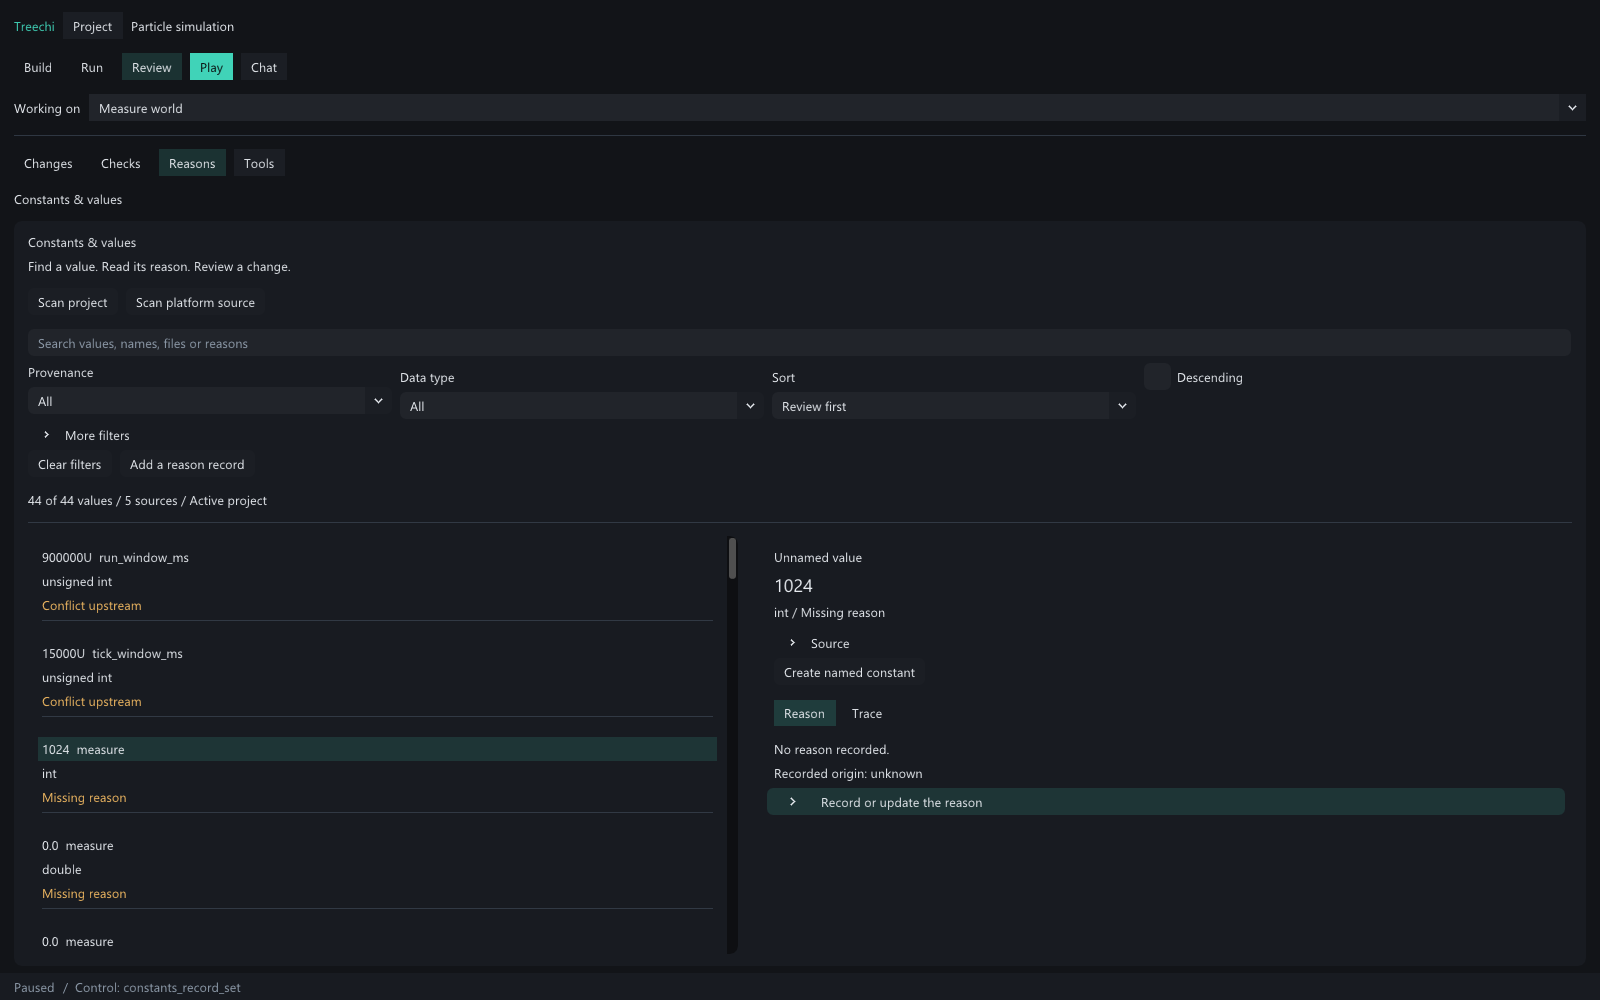
1/2Built in native Treechi. Scan numeric values, filter by recorded provenance and type, and review a named-constant draft. AI origin appears only when recorded. Development build shown with a synthetic fixture.
Read real values before writing claims
The same Claude Code report describes an agent stating a guessed result as fact when it could not access the run logs. A plausible explanation cannot replace a measurement.
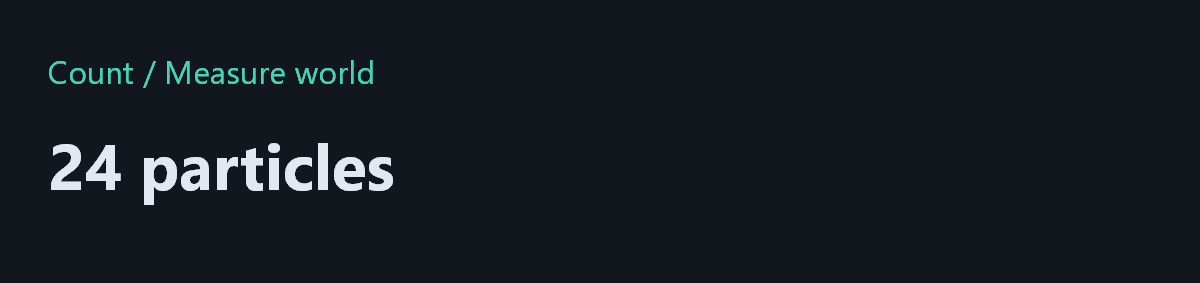
Treechi's gauge export turns stored readings into images for sharing. Open the data file for source and run details. Include a recorded formula when it helps explain the result.
Make review part of the workflow
Record the ask, inspect a draft, check the candidate, then accept the checked change. I designed these as connected steps so the request and evidence remain available at the point of review.
How the records and checks connect
- Request: Request records preserve the submitted wording and arrival channel. Requests relayed through an agent are marked attribution-unverified instead of being recorded as direct user input.
- Task: Each task records its origin, implementation, measurements, deliberate failure test and limits. Human decisions, agent proposals and review findings remain distinct.
- Regression check: Old and fixed code run against the same frozen fixture in isolated copies. A regression check must fail on the defect and pass on the fix.
- Commit: Treechi stages the declared files and tests that exact index before committing. A failed check refuses the commit, unstages the files and names the failure.
- Commit message: Commit messages separate the agent's account from “Treechi saw:” and “Treechi did not see:”, which record the platform's checks and their limits.
- Provenance query: A provenance query traces a component through its tasks, original request, modifying command and subsequent changes.
03 / The interface
Help the next decision stand out
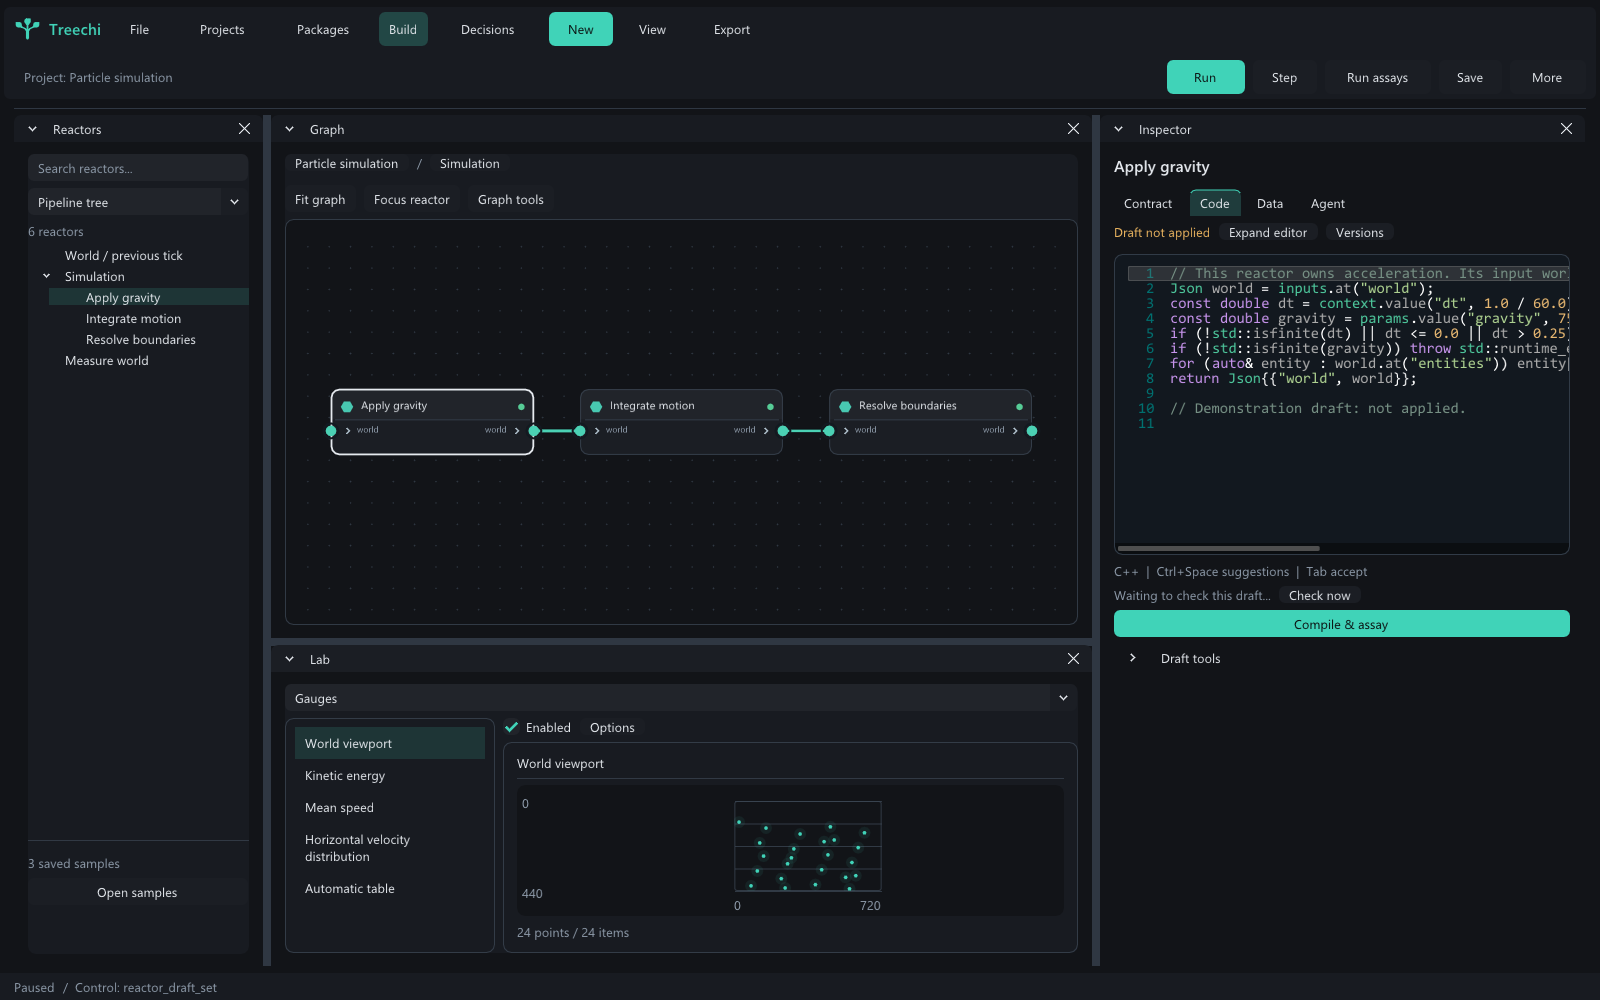
The workbench had too many tools competing for attention. I drew on Aspen’s task-specific environments to organize Build, Run and Review around the same project. Simulink’s source-linked diagnostics informed the Play flow: a blocking issue opens the affected reactor.
The project and selected reactor stay in place across views. Chat references open the actual reactor or reading in that same layout, preserving the current workspace. Back to chat returns to the conversation and its original selection.
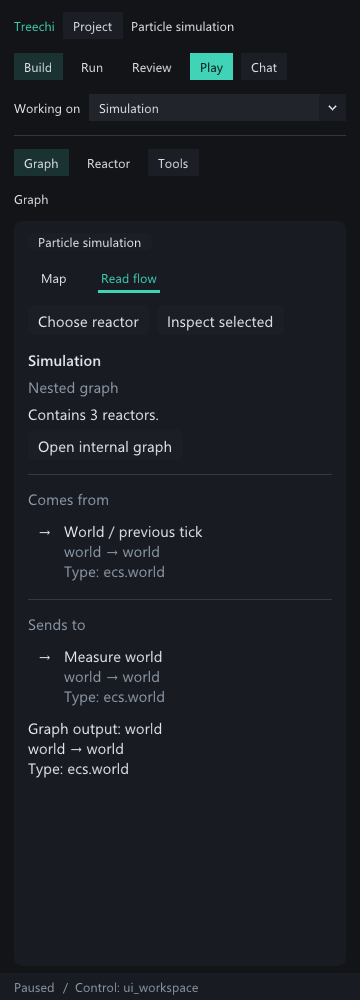
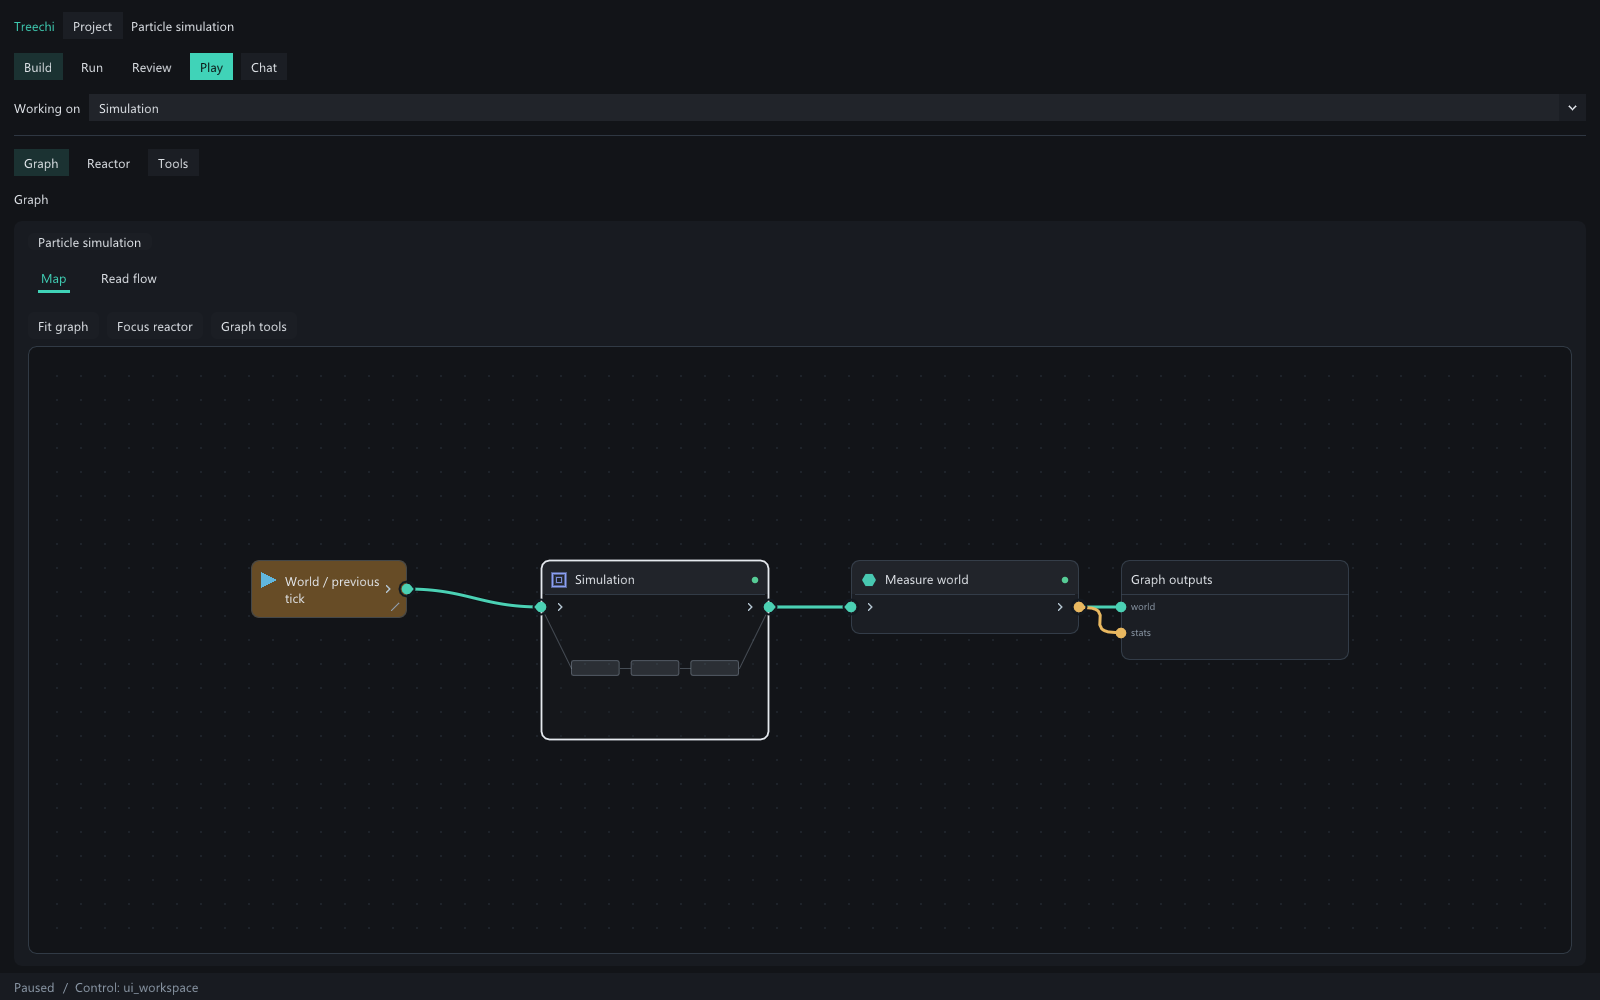
1/5Build keeps the graph and selected reactor together. Secondary creation and export tools are available as needed. Native development build shown with the public particles demo and a synthetic chat fixture.
Explore all 20 interface views
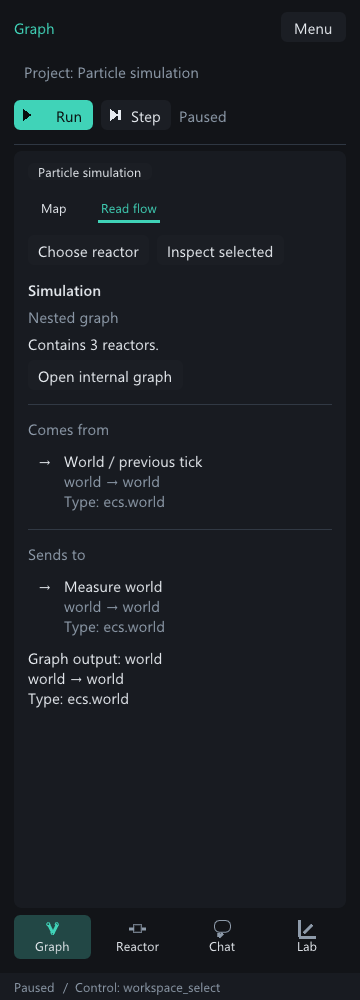
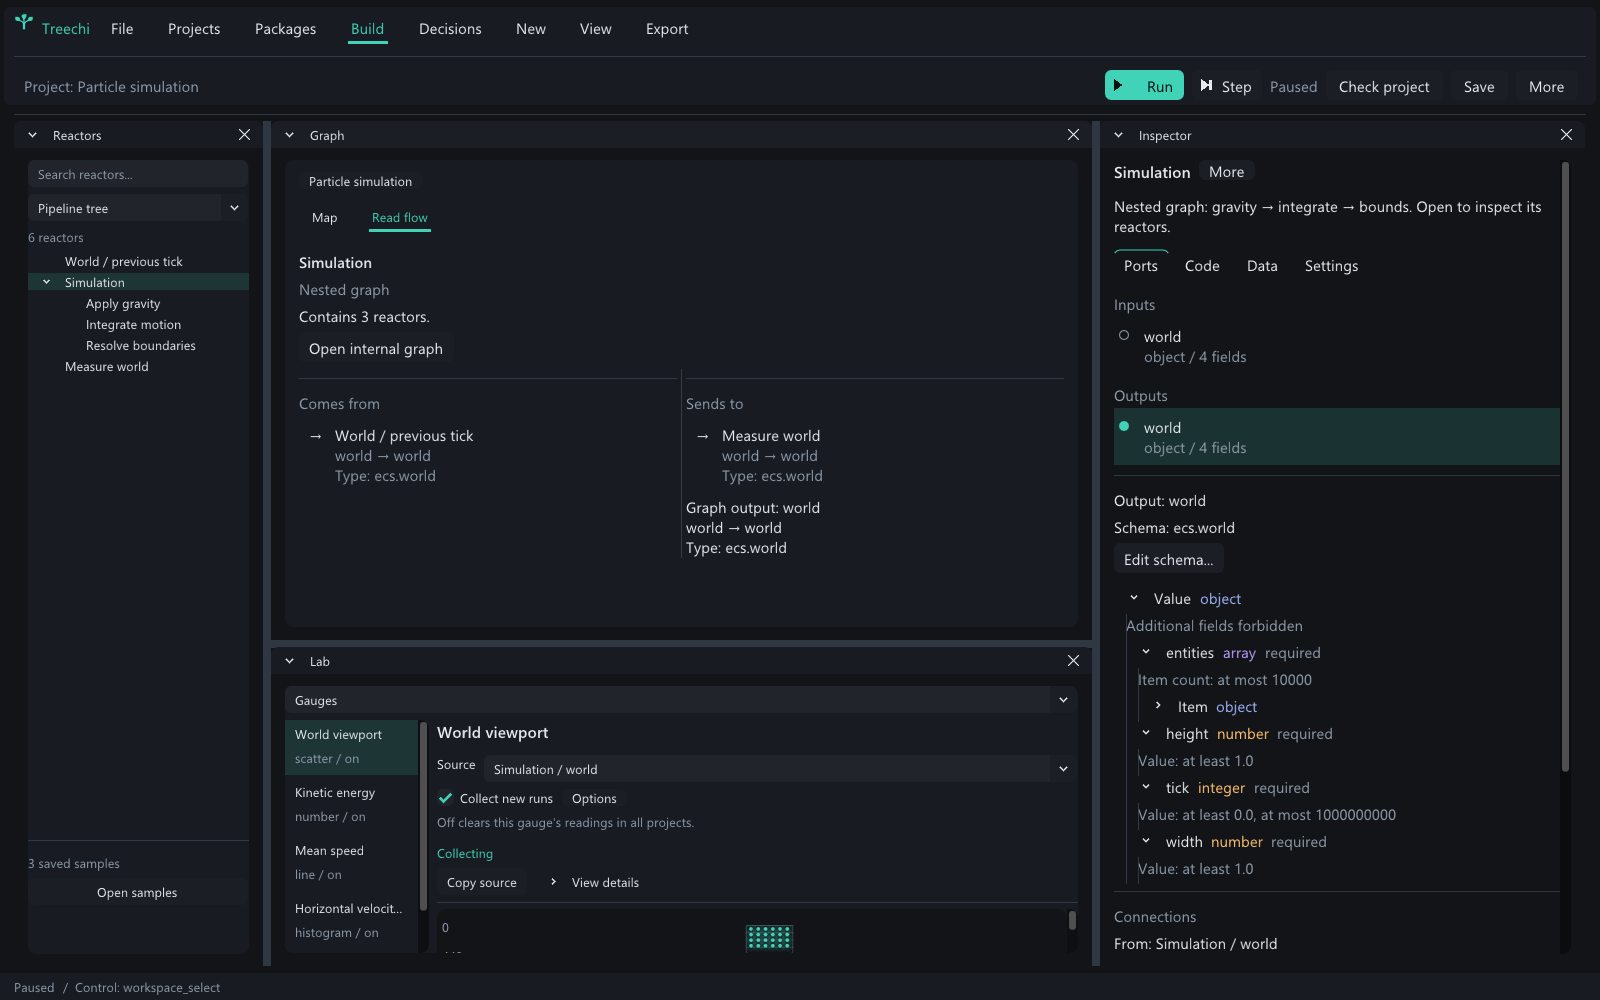
1/20Development preview: read where data comes from and where it goes, follow a connection, or open the selected reactor's internal graph. Map keeps spatial editing available. Private particle-simulation fixture; changes await integration into the running app.
04 / Decision history
Keep the reasons beside the work
Returning to a project should not mean rebuilding a decision from chat. I made the need, decision and change readable first. Evidence and Related hold the checks, limits, alternatives and affected parts. Diagrams remain available for tracing connections.
A similar experience · Codex issue #44829 · Astra 6 — read the report
“an explicitly rejected approach was recreated later”
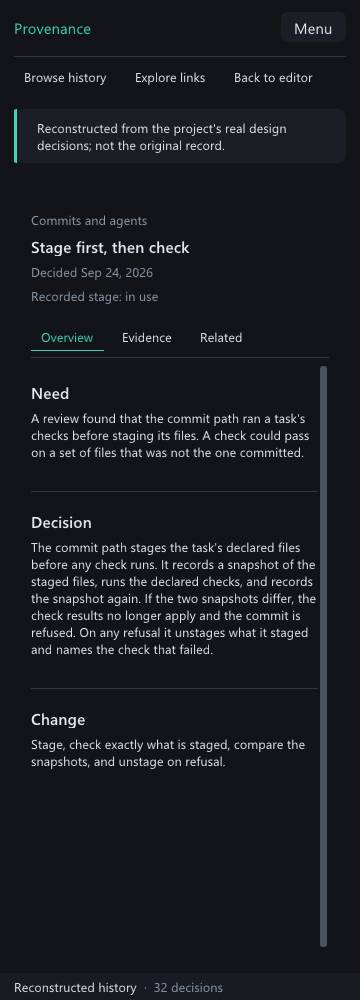
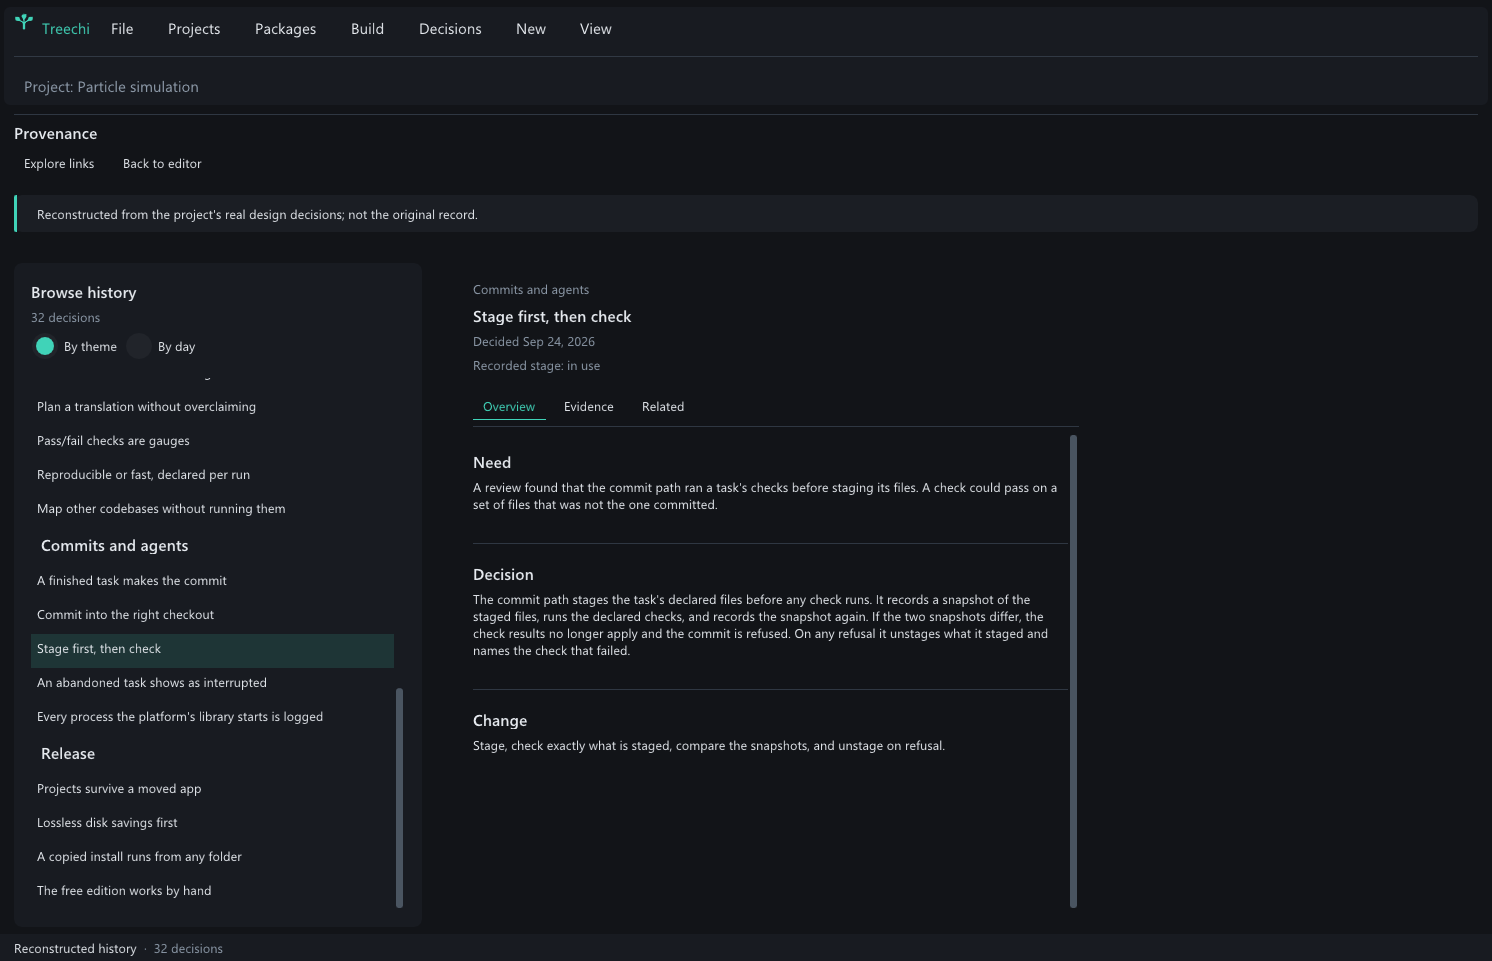
Explore the earlier diagram walkthrough
05 / Reflection
What the work demonstrates
The work connects three parts of review that were previously scattered: the request, the implementation and its acceptance evidence. The interface makes drafts and next actions visible, while the records give a reviewer a path back to the reason for a change.
This adds structure to maintain. I use summaries and progressive disclosure to make that structure easier to read. The screenshots and focused checks below show specific parts of the design; broader integration and release work remain unfinished.
Measured engineering results
70 / 70
steps matched
Same simulation, clearer structure
The original and nested CIP models produced the same values at every step. All 116 output ports and 23 feedback states were compared.
How it was checked
A development comparison on October 2, 2026 covered the original 55-reactor model and its nine-node top-level hierarchy. Two deliberately changed copies produced different outputs, confirming that the check detects broken wiring and changed starting state.
Read the measured data32 bytes
sent to the probe
Send only the inputs a component needs
A probe received only its bound inputs, even with 20,000 numbers elsewhere in the graph.
How it was checked
This two-node fixture measures payload size, not speed. The unused data stayed out of the probe's context.
8 / 8
snapshots restored
Restore the same history
All eight snapshots returned identical replies after a restart. Repeated content is stored once.
How it was checked
The development check used a backed-up platform-store copy. Identical history is stored by its content hash.
Engineering problems and trade-offs
I also found limits whose comments vouched for their own values. Giving each bound a provenance record, and reading code without comments, made its explanation traceable. A deliberately broken link made the check fail and name the bound; restoration passed. The follow-up fixes are still open. Compute policy is reproducible by default on the development branch; GPU use depends on measured benefit.
Intent is stored beside the code, not inside it
- Problem
- Comments describe what someone meant the code to do, and they drift from what it does. An agent can also write a comment that vouches for its own change.
- Response
- Each reactor keeps a revisioned intent record separate from its code. Applying code links it to the current intent revision, and review flags any drift between the two.
- Trade-off
- Two records to keep current instead of one. Review surfaces the gap instead of hiding it.
- Status
- Built.
Data travels between reactors as typed tables, not JSON text
- Problem
- Every call serialized its inputs and outputs as JSON text: four passes over the bytes per node per tick. On a long simulation run, one node averaged 849 ms a tick, and a single tick crossed the 1,500 ms budget and stopped the run.
- Response
- Columnar data travels as typed tables in binary frames and is read in place. Text is rendered only at the boundaries where a person reads it.
- Trade-off
- For 60,000 rows by 16 columns, build, transport and read fell from 188.8 ms to 48.7 ms. On small integers the fixed-width table is larger than compact binary arrays; the gain is the parsing it skips, not the bytes.
- Status
- Built.
Every schema edge gets a generated test
- Problem
- A 2,000-tick run stopped at tick 1,162. One component's schema allowed 4,096 ids and the next allowed 64. Every document was valid against its own schema until the population grew past 64.
- Response
- A schema probe generates inputs from each declared schema, recursively including nulls, runs each reactor on its own, and flags a downstream bound that is narrower than the one feeding it.
- Trade-off
- The probe is a separate run, not a per-tick check, so it has to be run to be useful.
- Status
- Built.
Validation is a setting, and its default depends on where the code runs
- Problem
- Checking every port against its schema on every tick took a tick from 9.0 ms to 57.1 ms, and an exported program paid the same cost.
- Response
- Port validation has three modes: always, preflight only and never. The workbench defaults to preflight, which proves structure once per revision. Exported programs default to never, and the generated header says so. Diagnostic logging stays in diagnosis mode, so exported programs carry none of it.
- Trade-off
- A value that goes wrong mid-run in an exported program is not caught there; preflight and the schema probe have to catch it first.
- Status
- Decided in September 2026; being built.
A limit needs a reason, not a round number
- Problem
- Of 3,219 declared bounds in one set of packages, 1,485 were numbers someone chose, and 7.6% of those carried any explanation. A 64 MiB transport cap had no basis beyond being round.
- Response
- Each bound gets a provenance record linked to its source, test, issue and decision. The transport cap is being replaced with a check that a frame is representable, plus explicit allocation errors. A timing measurement never authorizes truncating data, lowering precision or skipping validation.
- Trade-off
- Justifying the existing bounds is ongoing work. A bound without a reason is flagged rather than accepted.
- Status
- Provenance records built; cap replacement agreed.
Exported C++ matches the workbench where it can, and says where it cannot
- Problem
- Treechi is meant to produce standalone programs, and an export is only trustworthy if it runs the way the workbench ran it.
- Response
- Export emits each reactor as a function carrying its own code, runs composites in the engine's readiness order with no scheduler in the generated code, commits feedback only after a whole successful tick, and links the platform's own validator. Every place the exported run cannot match is stated.
- Trade-off
- Exported programs are single-threaded and need Treechi's runtime libraries.
- Status
- Stage 1 built.
Measure before parallelizing
- Problem
- I wanted input handling in an interactive project to run without waiting on the rest of the graph, and asked whether the scheduler could run in parallel.
- Response
- Reading the graph showed input sat at the head of the tick: 46 of the other 56 nodes depended on it within the same tick, so running ready nodes in parallel could not shorten the path from input to result. The need was cadence, not threads. I built lanes: parts of the graph that tick on their own clock and read each other's last completed output, modeled on the split between a fixed simulation tick and a per-frame render. The root lane's tick runs on its own thread over a snapshot of the graph, so an edit never waits on it.
- Trade-off
- Lanes add a second clock to reason about, and a wire that crosses lanes behaves like feedback. Parallel execution inside a lane is a separate piece of work.
- Status
- Lanes built on the main line; the served build picks them up at the next merge. Parallel execution inside a lane is being built.
Supporting example: a complete simulation
The clean-in-place model gave me a demanding example: 55 nodes and 275 connections, with changing routes, pump conditions and checks against known answers. It exposed the need to group a large graph without losing its behavior or saved evidence. The cleaned hierarchy is still being transferred to the complete original project.
This is a model with illustrative assumptions, not plant data. The existing captures below show the original complete model; they do not show the proposed grouping as completed.
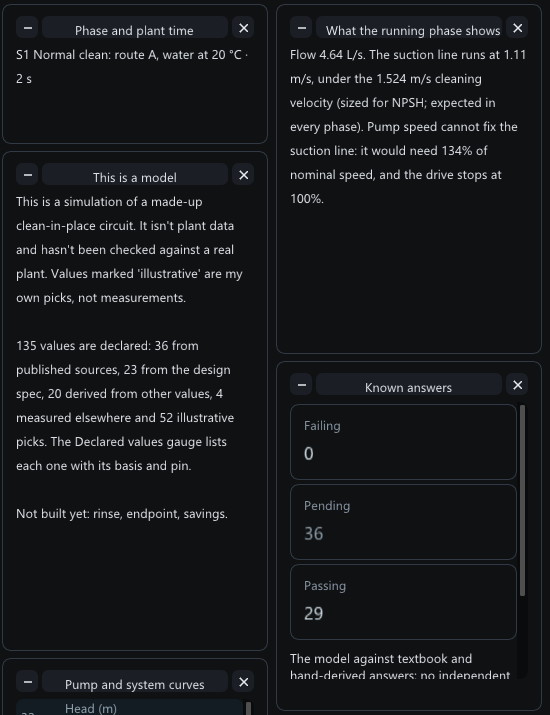
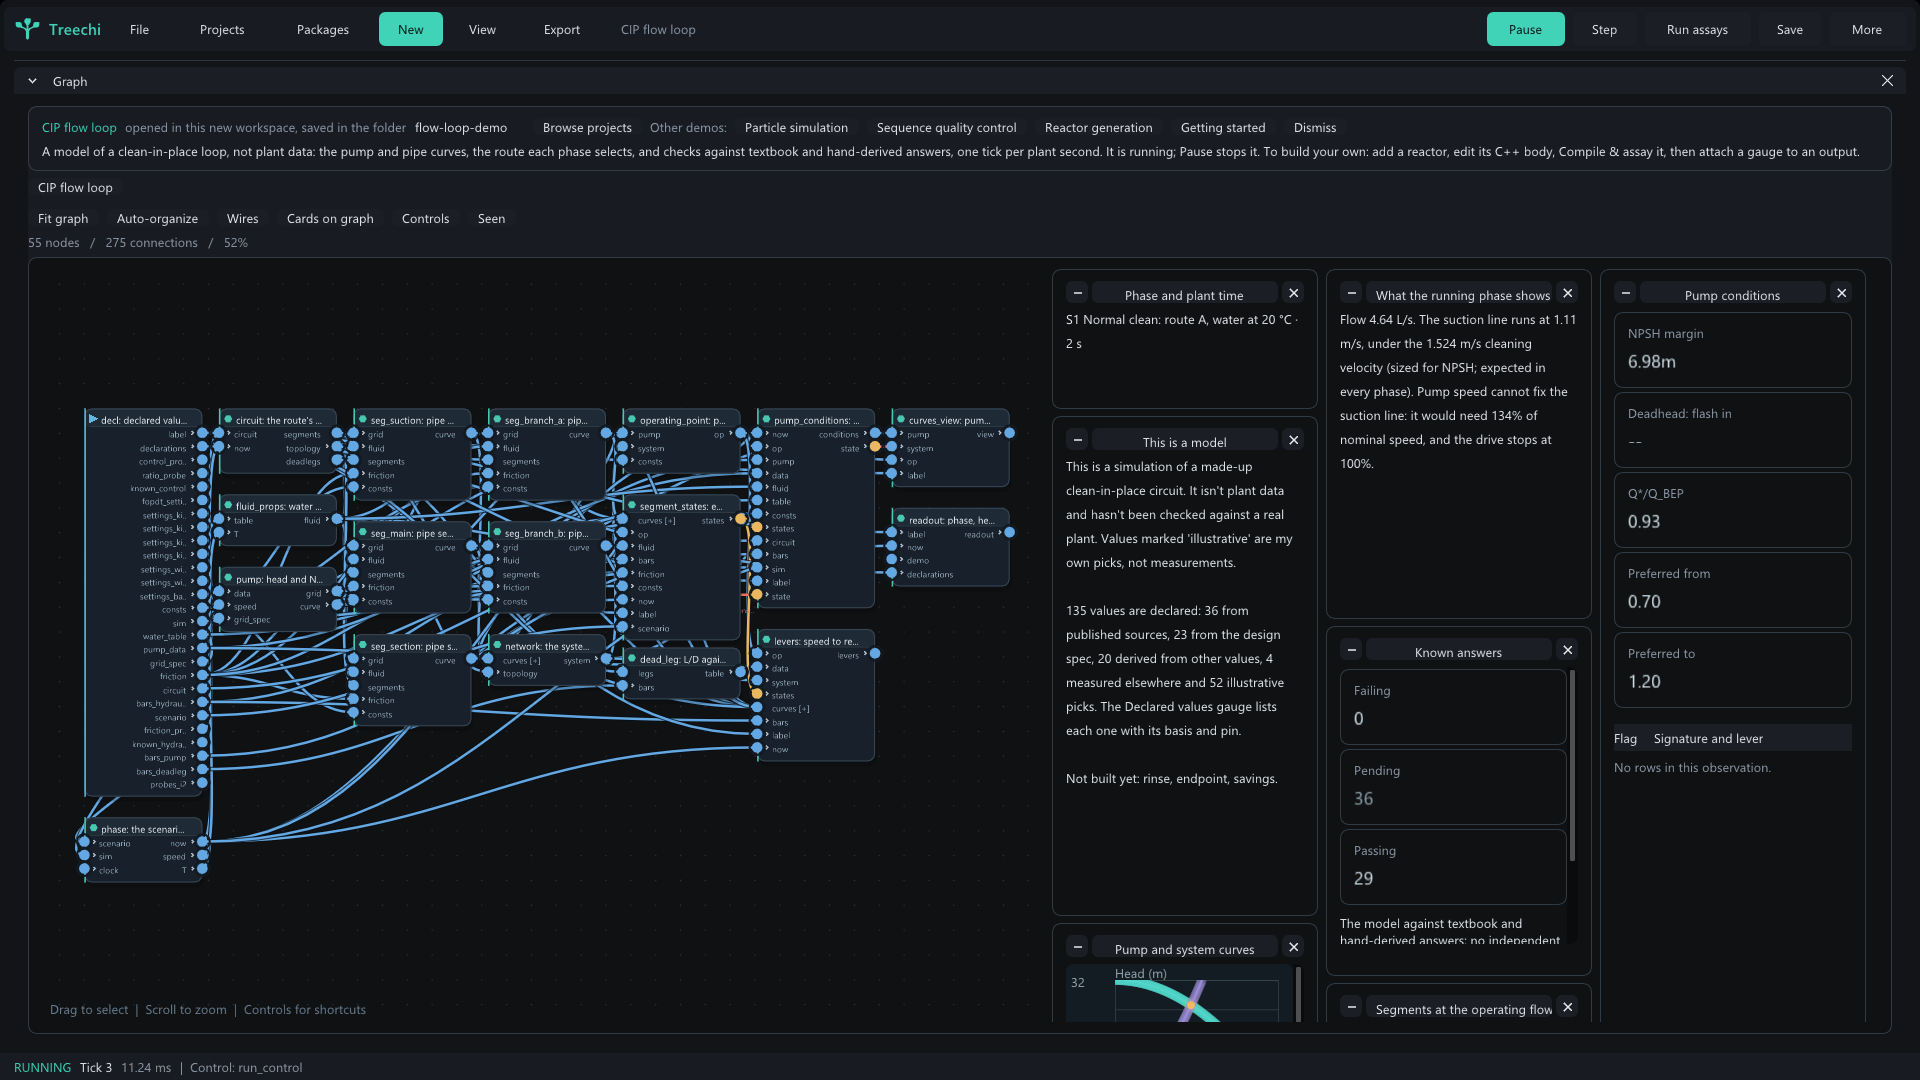
1/6A normal clean on route A with water at 20 °C. The suction line runs under the 1.524 m/s cleaning velocity; it is sized for NPSH, so that is expected in every phase.
Current scope and remaining work
- Private Windows x64 alpha. Portable packaging, bundled clang, signing and clean-machine acceptance are not release-complete.
- Reactor code runs with the user's permissions. File, network and process scans are warnings, not a security sandbox.
- Lanes run parts of a graph on their own clocks; nodes within a lane still run one at a time. Compute kernels can run in parallel. Exported C++ is single-threaded and requires Treechi runtime libraries.
- The currently served host uses CLI/MCP for request, task and provenance authoring. Window forms and queries are tested on a separate release branch; integration and full manual parity remain open.
- Broader self-hosting and export coverage remain in progress.
- Current captures identify development previews. The provenance screenshot uses a reconstructed history. Complete context notifications, faithful project reorganization and broader integration remain in progress.